[译]YOLOE: Real-Time Seeing Anything
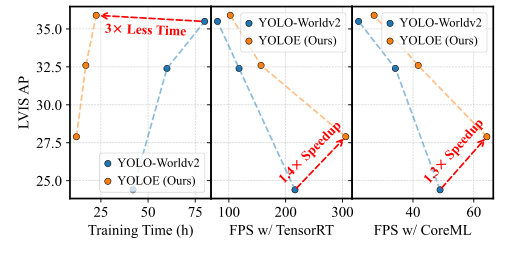
YOLOE 将开放词汇检测与分割统一进单个实时模型:RepRTA 处理文本提示、SAVPE 编码视觉提示、LRPC 支持无提示检索,在 LVIS 上以 YOLO-Worldv2 三分之一的训练成本反超其 3.5 AP。
原文地址:YOLOE: Real-Time Seeing Anything
官方实现:THU-MIG/yoloe
Abstract
Object detection and segmentation are widely employed in computer vision applications, yet conventional models like YOLO series, while efficient and accurate, are limited by predefined categories, hindering adaptability in open scenarios. Recent open-set methods leverage text prompts, visual cues, or prompt-free paradigm to overcome this, but often compromise between performance and efficiency due to high computational demands or deployment complexity. In this work, we introduce YOLOE, which integrates detection and segmentation across diverse open prompt mechanisms within a single highly efficient model, achieving real-time seeing anything. For text prompts, we propose Re-parameterizable Region-Text Alignment (RepRTA) strategy. It refines pretrained textual embeddings via a re-parameterizable lightweight auxiliary network and enhances visual-textual alignment with zero inference and transferring overhead. For visual prompts, we present Semantic-Activated Visual Prompt Encoder (SAVPE). It employs decoupled semantic and activation branches to bring improved visual embedding and accuracy with minimal complexity. For prompt-free scenario, we introduce Lazy Region-Prompt Contrast (LRPC) strategy. It utilizes a built-in large vocabulary and specialized embedding to identify all objects, avoiding costly language model dependency. Extensive experiments show YOLOE’s exceptional zero-shot performance and transferability with high inference efficiency and low training cost. Notably, on LVIS, with 3× less training cost and 1.4× inference speedup, YOLOE-v8-S surpasses YOLO-Worldv2-S by 3.5 AP. When transferring to COCO, YOLOE-v8-L achieves 0.6 APb and 0.4 APm gains over closed-set YOLOv8-L with nearly 4× less training time. Code and models are available at https://github.com/THU-MIG/yoloe.
目标检测和分割广泛应用于计算机视觉,但 YOLO 系列等传统模型虽然高效且准确,却受限于预定义类别,阻碍了在开放场景中的适应性。近期的开放集方法利用文本提示、视觉线索或无提示范式来克服这一问题,但由于高计算需求或部署复杂性,往往在性能和效率之间做出妥协。本文提出 YOLOE,在单个高效模型中集成了跨多种开放提示机制的检测和分割,实现实时”看见一切”。针对文本提示,我们提出可重参数化的区域-文本对齐(RepRTA)策略,通过可重参数化的轻量辅助网络优化预训练文本嵌入,在零推理和零迁移开销下增强视觉-文本对齐。针对视觉提示,我们提出语义激活的视觉提示编码器(SAVPE),采用解耦的语义分支和激活分支,以极低复杂度带来更好的视觉嵌入和精度。针对无提示场景,我们引入惰性区域-提示对比(LRPC)策略,利用内置大词汇表和专用嵌入识别所有物体,避免了对昂贵语言模型的依赖。大量实验表明,YOLOE 具有出色的零样本性能和可迁移性,同时具备高推理效率和低训练成本。值得注意的是,在 LVIS 上,YOLOE-v8-S 以 3 倍少的训练成本和 1.4 倍推理加速超越 YOLO-Worldv2-S 达 3.5 AP。迁移到 COCO 时,YOLOE-v8-L 以近 4 倍少的训练时间,相比闭集 YOLOv8-L 获得 0.6 APb 和 0.4 APm 的提升。代码和模型见 https://github.com/THU-MIG/yoloe。
1. Introduction
Object detection and segmentation are foundational tasks in computer vision [15, 48], with widespread applications spanning autonomous driving [2], medical analyses [55], and robotics [8], etc. Traditional approaches like YOLO series [1, 3, 21, 47], have leveraged convolutional neural networks to achieve real-time remarkable performance. However, their dependence on predefined object categories constrains flexibility in practical open scenarios. Such scenarios increasingly demand models capable of detecting and segmenting arbitrary objects guided by diverse prompt mechanisms, such as texts, visual cues, or without prompt.
目标检测和分割是计算机视觉的基础任务 [15, 48],广泛应用于自动驾驶 [2]、医学分析 [55] 和机器人 [8] 等领域。YOLO 系列 [1, 3, 21, 47] 等传统方法利用卷积神经网络实现了实时的出色性能。然而,它们对预定义物体类别的依赖限制了在实际开放场景中的灵活性。这类场景越来越需要能够检测和分割任意物体的模型,并由多样的提示机制引导,例如文本、视觉线索或无提示。
Given this, recent efforts have shifted towards enabling models to generalize for open prompts [5, 20, 49, 80]. They target single prompt type, e.g., GLIP [32], or multiple prompt types in a unified way, e.g., DINO-X [49]. Specifically, with region-level vision-language pretraining [32, 37, 65], text prompts are usually processed by text encoder to serve as contrastive objectives for region features [20, 49], achieving recognition for arbitrary categories, e.g., YOLO-World [5]. For visual prompts, they are often encoded as class embeddings tied to specified regions for identifying similar objects, by the interaction with image features or language-aligned visual encoder [5, 19, 30, 49], e.g., T-Rex2 [20]. In prompt-free scenario, existing methods typically integrate language models, finding all objects and generating the corresponding category names conditioned on region features sequentially [49, 62], e.g., GenerateU [33].
为此,近期的研究转向让模型具备开放提示的泛化能力 [5, 20, 49, 80]。它们或针对单一提示类型,如 GLIP [32],或以统一方式支持多种提示类型,如 DINO-X [49]。具体来说,借助区域级视觉-语言预训练 [32, 37, 65],文本提示通常由文本编码器处理,作为区域特征的对比目标 [20, 49],实现对任意类别的识别,例如 YOLO-World [5]。对于视觉提示,它们通常通过与图像特征或语言对齐的视觉编码器交互,将提示编码为与指定区域绑定的类别嵌入,用于识别相似物体 [5, 19, 30, 49],例如 T-Rex2 [20]。在无提示场景中,现有方法通常集成语言模型,以区域特征为条件依次找到所有物体并生成对应的类别名称 [49, 62],例如 GenerateU [33]。
Despite notable advancements, a single model that supports diverse open prompts for arbitrary objects with high efficiency and accuracy is still lacking. For example, DINO-X [49] features a unified architecture, which, however, incurs resource-intensive training and inference overhead. Additionally, individual designs for different prompts in separate works exhibit suboptimal trade-offs between performance and efficiency, making it difficult to directly combine them into one model.
尽管取得了显著进展,仍然缺少一个能以高效率和精度支持任意物体、多样开放提示的单一模型。例如,DINO-X [49] 具备统一架构,但带来了资源密集型的训练和推理开销。此外,不同工作中针对不同提示的独立设计在性能和效率之间呈现出次优的权衡,难以直接组合到一个模型中。
For example, text-prompted approaches often incur substantial computational overhead when incorporating large vocabularies, due to complexity of cross-modality fusion [5, 32, 37, 49]. Visual-prompted methods usually compromise deployability on edge devices owing to the transformer-heavy design or reliance on additional visual encoder [20, 30, 67]. Prompt-free ways, meanwhile, depend on large language models, introducing considerable memory and latency costs [33, 49].
例如,文本提示方法在引入大词汇表时往往产生大量计算开销,原因是跨模态融合的复杂性 [5, 32, 37, 49]。视觉提示方法通常因重 Transformer 设计或依赖额外的视觉编码器而牺牲了在边缘设备上的可部署性 [20, 30, 67]。同时,无提示方式依赖大语言模型,带来了可观的显存和延迟成本 [33, 49]。
In light of these, in this paper, we introduce YOLOE(ye), a highly efficient, unified, and open object detection and segmentation model, like human eye, under different prompt mechanisms, like texts, visual inputs, and prompt-free paradigm. We begin with YOLO models with widely proven efficacy. For text prompts, we propose a Re-parameterizable Region-Text Alignment (RepRTA) strategy, which employs a lightweight auxiliary network to improve pretrained textual embeddings for better visual-semantic alignment. During training, pre-cached textual embeddings require only the auxiliary network to process text prompts, incurring low additional cost compared with closed-set training. At inference and transferring, auxiliary network is seamlessly re-parameterized into the classification head, yielding an architecture identical to YOLOs with zero overhead. For visual prompts, we design a Semantic-Activated Visual Prompt Encoder (SAVPE). By formalizing regions of interest as masks, SAVPE fuses them with multi-scale features from PAN to produce grouped prompt-aware weights in low dimension in an activation branch and extract prompt-agnostic semantic features in a semantic branch. Prompt embeddings are derived through aggregation of them, resulting in favorable performance with minimal complexity. For prompt-free scenario, we introduce Lazy Region-Prompt Contrast (LRPC) strategy. Without relying on costly language models, LRPC leverages a specialized prompt embedding to find all objects and a built-in large vocabulary for category retrieval. By matching only anchor points with identified objects against the vocabulary, LRPC ensures high performance with low overhead.
鉴于上述情况,本文提出 YOLOE,一个高效、统一、开放的物体检测和分割模型,如同人眼一样,在文本、视觉输入和无提示范式等不同提示机制下工作。我们从已被广泛验证有效的 YOLO 模型出发。针对文本提示,我们提出可重参数化的区域-文本对齐(RepRTA)策略,利用轻量辅助网络改进预训练文本嵌入,以获得更好的视觉-语义对齐。训练期间,预先缓存的文本嵌入只需辅助网络处理文本提示,与闭集训练相比额外成本很低。在推理和迁移时,辅助网络可以无缝重参数化进分类头,得到与 YOLO 完全一致的架构,零开销。针对视觉提示,我们设计了语义激活的视觉提示编码器(SAVPE)。SAVPE 将感兴趣区域形式化为掩膜,将其与 PAN 的多尺度特征融合,在激活分支中以低维生成分组的提示感知权重,并在语义分支中提取与提示无关的语义特征。通过两者的聚合得到提示嵌入,以最小的复杂度实现良好的性能。针对无提示场景,我们引入惰性区域-提示对比(LRPC)策略。LRPC 不依赖昂贵的语言模型,利用专用提示嵌入找到所有物体,并通过内置大词汇表进行类别检索。通过仅将有物体的锚点与词汇表匹配,LRPC 以低开销确保了高性能。
Thanks to them, YOLOE excels in detection and segmentation across diverse open prompt mechanisms within one model, enjoying high inference efficiency and low training cost. Notably, as shown in Fig. 1, under 3× less training cost, YOLOE-v8-S significantly outperforms YOLO-Worldv2-S [5] by 3.5 AP on LVIS [14], with 1.4× and 1.3× inference speedups on T4 and iPhone 12, respectively. In visual-prompted and prompt-free settings, YOLOE-v8-L outperforms T-Rex2 by 3.3 APr and GenerateU by 0.4 AP with 2× less training data and 6.3× fewer parameters, respectively. For transferring to COCO [34], YOLOE-v8-M / L outperforms YOLOv8-M / L by 0.4 / 0.6 APb and 0.4 / 0.4 APm with nearly 4× less training time. We hope that YOLOE can establish a strong baseline and inspire further advancements in real-time open prompt-driven vision tasks.
得益于这些设计,YOLOE 在单一模型中出色地完成了跨多种开放提示机制的检测和分割,具备高推理效率和低训练成本。值得注意的是,如图 1 所示,YOLOE-v8-S 以 3 倍少的训练成本,在 LVIS [14] 上显著超越 YOLO-Worldv2-S [5] 达 3.5 AP,并在 T4 和 iPhone 12 上分别获得 1.4 倍和 1.3 倍的推理加速。在视觉提示和无提示设置下,YOLOE-v8-L 分别以 2 倍少的训练数据和 6.3 倍少的参数量,超越 T-Rex2 达 3.3 APr、超越 GenerateU 达 0.4 AP。迁移到 COCO [34] 时,YOLOE-v8-M / L 以近 4 倍少的训练时间,相比 YOLOv8-M / L 提升 0.4 / 0.6 APb 和 0.4 / 0.4 APm。我们希望 YOLOE 能成为一个强大的基线,推动实时开放提示驱动视觉任务的进一步发展。
2. Related Work
2.1 传统检测和分割
Traditional approaches for object detection and segmentation primarily operate under closed-set paradigms. Early two-stage frameworks [4, 12, 15, 48], exemplified by Faster R-CNN [48], introduce region proposal networks (RPNs) followed by region-of-interest (ROI) classification and regression. Meanwhile, single-stage detectors [10, 35, 38, 56, 72] prioritizes speed through grid-based predictions within a single network. The YOLO series [1, 21, 27, 47, 59, 60] plays a significant role in this paradigm and are widely used in real world. Moreover, DETR [28] and its variants [28, 69, 77] mark a major shift by removing heuristic-driven components with transformer-based architectures. To achieve finer-grained results, existing instance segmentation methods predict pixel-level masks rather than bounding box coordinates [15]. For this, YOLACT [3] facilitates real-time instance segmentation through integration of prototype masks and mask coefficients. Based on DINO [69], MaskDINO [29] utilizes query embeddings and a high-resolution pixel embedding map to produce binary masks.
传统的物体检测和分割方法主要在闭集范式下运行。以 Faster R-CNN [48] 为代表的早期两阶段框架 [4, 12, 15, 48],先引入区域提议网络(RPN),再进行感兴趣区域(ROI)的分类和回归。与此同时,单阶段检测器 [10, 35, 38, 56, 72] 通过在单一网络中进行基于网格的预测来优先保证速度。YOLO 系列 [1, 21, 27, 47, 59, 60] 在该范式中扮演了重要角色,并在现实世界中得到广泛应用。此外,DETR [28] 及其变体 [28, 69, 77] 通过基于 Transformer 的架构移除了启发式组件,标志着重大转变。为了获得更细粒度的结果,现有实例分割方法预测像素级掩膜而非边界框坐标 [15]。为此,YOLACT [3] 通过原型掩膜和掩膜系数的结合实现了实时实例分割。基于 DINO [69],MaskDINO [29] 利用查询嵌入和高分辨率像素嵌入图生成二值掩膜。
2.2 文本提示检测和分割
Recent advancements in open-vocabulary object detection [13, 25, 61, 68, 74–76] have focused on detecting novel categories by aligning visual features with textual embeddings. Specifically, GLIP [32] unifies object detection and phrase grounding through grounded pre-training on large-scale image-text pairs, demonstrating robust zero-shot performance. DetCLIP [65] facilitates open-vocabulary learning by enriching the concepts with descriptions. Besides, Grounding DINO [37] enhances this by integrating cross-modality fusion into DINO, improving alignment between text prompts and visual representations. YOLO-World [5] further shows the potential of pretraining small detectors with open recognition capabilities based on the YOLO architecture. YOLO-UniOW [36] builds upon YOLO-World by leveraging the adaptive decision-learning strategy. Similarly, several open-vocabulary instance segmentation models [11, 18, 26, 45, 63] learn rich visual-semantic knowledge from advanced foundation models to perform segmentation on novel object categories. For example, X-Decoder [79] and OpenSeeD [71] explore both the open-vocabulary detection and segmentation tasks. APE [54] introduces a universal visual perception model that aligns and prompts all objects in image using various text prompts.
开放词汇物体检测的近期进展 [13, 25, 61, 68, 74–76] 聚焦于通过将视觉特征与文本嵌入对齐来检测新类别。具体来说,GLIP [32] 通过在大规模图文对上进行 grounding 预训练,统一了物体检测和短语定位,展现出稳健的零样本性能。DetCLIP [65] 通过用描述丰富概念来促进开放词汇学习。此外,Grounding DINO [37] 将跨模态融合集成到 DINO 中,改善了文本提示与视觉表示之间的对齐。YOLO-World [5] 进一步展示了基于 YOLO 架构预训练具有开放识别能力的小型检测器的潜力。YOLO-UniOW [36] 在 YOLO-World 的基础上利用自适应决策学习策略。类似地,若干开放词汇实例分割模型 [11, 18, 26, 45, 63] 从先进的基础模型中学习丰富的视觉-语义知识,以对新物体类别进行分割。例如,X-Decoder [79] 和 OpenSeeD [71] 同时探索开放词汇检测和分割任务。APE [54] 提出了一个通用视觉感知模型,利用各种文本提示对图像中的所有物体进行对齐和提示。
2.3 视觉提示检测和分割
While text prompts offer a generic description, certain objects can be challenging to describe with language alone, such as those requiring specialized domain knowledge. In such cases, visual prompts can guide detection and segmentation more flexibly and specifically, complementing text prompts [19, 20]. OV-DETR [67] and OWL-ViT [41] leverage CLIP encoders to process text and image prompts. MQ-Det [64] augments text queries with class-specific visual information from query images. DINOv [30] explores visual prompts as in-context examples for generic and referring vision tasks. T-Rex2 [20] integrates visual and text prompts by region-level contrastive alignment. For segmentation, based on large-scale data, SAM [23] presents a flexible and strong model that can be prompted interactively and iteratively. SEEM [80] further explores segmenting objects with more various prompt types. Semantic-SAM [31] excels in semantic comprehension and granularity detection, handling both panoptic and part segmentation tasks.
虽然文本提示提供了通用描述,但某些物体仅靠语言难以描述,例如需要专业知识领域的物体。在这种情况下,视觉提示可以更灵活、更具体地引导检测和分割,作为文本提示的补充 [19, 20]。OV-DETR [67] 和 OWL-ViT [41] 利用 CLIP 编码器处理文本和图像提示。MQ-Det [64] 用来自查询图像的类别特定视觉信息增强文本查询。DINOv [30] 将视觉提示作为上下文示例探索通用和指代视觉任务。T-Rex2 [20] 通过区域级对比对齐集成视觉和文本提示。对于分割,基于大规模数据,SAM [23] 提出了一个灵活而强大的模型,可以交互式、迭代式地进行提示。SEEM [80] 进一步探索了用更多样化的提示类型分割物体。Semantic-SAM [31] 在语义理解和粒度检测方面表现出色,同时处理全景和部件分割任务。
2.4 无提示检测和分割
Existing approaches still depend on explicit prompts during inference for open-set detection and segmentation. To address this limitation, several works [33, 40, 49, 62, 66] explore integrating with generative language models to produce object descriptions for all found objects. For instance, GRiT [62] employs a text decoder for both dense captioning and object detection tasks. DetCLIPv3 [66] trains an object captioner on large-scale data, enabling model to generate rich label information. GenerateU [33] leverages the language model to generate object names in a free-form way.
现有方法在开放集检测和分割的推理过程中仍依赖显式提示。为了解决这一局限,若干工作 [33, 40, 49, 62, 66] 探索与生成式语言模型集成,为所有找到的物体生成物体描述。例如,GRiT [62] 使用文本解码器同时完成密集描述和物体检测任务。DetCLIPv3 [66] 在大规模数据上训练物体描述器,使模型能够生成丰富的标签信息。GenerateU [33] 利用语言模型以自由形式生成物体名称。
To the best of our knowledge, aside from DINO-X [49], few efforts have achieved object detection and segmentation across various open prompt mechanisms within a single architecture. However, DINO-X entails extensive training cost and notable inference overhead, severely constraining the practicality for real-world edge deployments. In contrast, our YOLOE aims to deliver an efficient and unified model that enjoys real-time performance and efficiency with easy deployability.
据我们所知,除 DINO-X [49] 外,很少有工作能在单一架构内实现跨各种开放提示机制的物体检测和分割。然而,DINO-X 需要大量的训练成本和显著的推理开销,严重制约了其在现实世界边缘部署中的实用性。相比之下,我们的 YOLOE 旨在提供一个高效统一的模型,兼具实时性能、效率和易部署性。
3. Methodology
3.1 模型架构
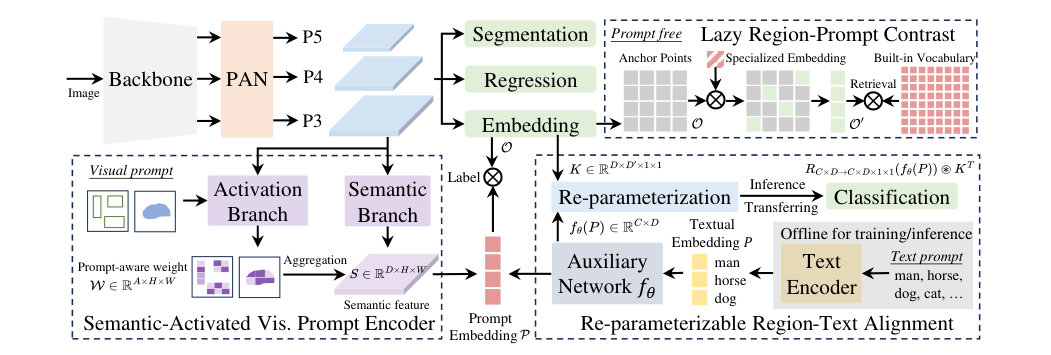
As shown in Fig. 2, YOLOE adopts the typical YOLOs’ architecture [1, 21, 47], consisting of backbone, PAN, regression head, segmentation head, and object embedding head. The backbone and PAN extracts multi-scale features for the image. For each anchor point, the regression head predicts the bounding box for detection, and the segmentation head produces the prototype and mask coefficients for segmentation [3]. The object embedding head follows the structure of classification head in YOLOs, except that the output channel number of last 1× convolution layer is changed from the class number in closed-set scenario to the embedding dimension. Meanwhile, given text and visual prompts, we employ RepRTA and SAVPE to encode them as normalized prompt embeddings P, respectively. They serve as the classification weights and contrast with the anchor points’ object embeddings O to obtain category labels. The process can be formalized as
如图 2 所示,YOLOE 采用典型的 YOLO 架构 [1, 21, 47],由骨干网络、PAN、回归头、分割头和物体嵌入头组成。骨干网络和 PAN 为图像提取多尺度特征。对于每个锚点,回归头预测用于检测的边界框,分割头生成用于分割的原型和掩膜系数 [3]。物体嵌入头沿用 YOLO 中分类头的结构,只是最后一层 1×1 卷积的输出通道数从闭集场景中的类别数改为嵌入维度。同时,给定文本和视觉提示,我们分别使用 RepRTA 和 SAVPE 将它们编码为归一化的提示嵌入 P。它们作为分类权重,与锚点的物体嵌入 O 进行对比以获得类别标签。该过程可以形式化为:
where N denotes the number of anchor points, C indicates the number of prompts, and D means the feature dimension of embeddings, respectively.
其中 N 表示锚点数量,C 表示提示数量,D 表示嵌入的特征维度。
3.2 可重参数化的区域-文本对齐
In open-set scenarios, the alignment between textual and object embeddings determines the accuracy of identified categories. Prior works usually introduce complex cross-modality fusion to improve the visual-textual representation for better alignment [5, 37]. However, these ways incur notable computational overhead, especially with large number of texts. Given this, we present Re-parameterizable Region-Text Alignment (RepRTA) strategy, which improves pretrained textual embeddings during training through the re-parameterizable lightweight auxiliary network. The alignment between textual and anchor points’ object embeddings can be enhanced with zero inference and transferring cost.
在开放集场景中,文本嵌入与物体嵌入之间的对齐决定了识别类别的准确性。先前的工作通常引入复杂的跨模态融合来改进视觉-文本表示,以获得更好的对齐 [5, 37]。然而,这些方法带来了显著的计算开销,尤其是在文本数量较多时。为此,我们提出可重参数化的区域-文本对齐(RepRTA)策略,在训练期间通过可重参数化的轻量辅助网络改进预训练文本嵌入。文本与锚点物体嵌入之间的对齐可以在零推理和零迁移成本下得到增强。
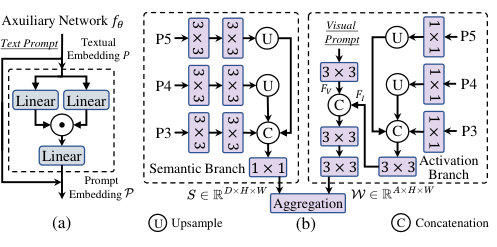
Specifically, with the text prompts of T with length of C, we first employ the CLIP text encoder [44, 57] to obtain pretrained textual embedding P = TextEncoder(T). Before training, we cache all embeddings of texts in datasets in advance and the text encoder can be removed with no extra training cost. Meanwhile, as shown in Fig. 3.(a), we introduce a lightweight auxiliary network fθ with only one feed forward block [53, 58], where θ indicates the trainable parameters and introduces low overhead compared with closed-set training. It derives the enhanced textual embedding P = fθ(P) ∈ R C×D for contrasting with the anchor points’ object embedding during training, leading to improved visual-semantic alignment. Let K ∈ R D×D′×1×1 be the kernel parameters of last convolution layer with input features I ∈ R D′×H×W in the object embedding head, ⊛ be the convolution operator, and R be the reshape function, we have
具体来说,对于长度为 C 的文本提示 T,我们首先使用 CLIP 文本编码器 [44, 57] 获得预训练文本嵌入 P = TextEncoder(T)。在训练之前,我们预先缓存数据集中所有文本的嵌入,文本编码器可以被移除,不产生额外训练成本。同时,如图 3.(a) 所示,我们引入一个轻量辅助网络 fθ,仅包含一个前馈块 [53, 58],其中 θ 表示可训练参数,与闭集训练相比引入的开销很低。它推导出增强的文本嵌入 P = fθ(P) ∈ R C×D,用于在训练期间与锚点的物体嵌入进行对比,从而改进视觉-语义对齐。设 K ∈ R D×D′×1×1 为物体嵌入头中最后一层卷积层的核参数,输入特征为 I ∈ R D′×H×W,⊛ 为卷积算子,R 为 reshape 函数,则有:
Moreover, after training, the auxiliary network can be re-parameterized with the object embedding head into the identical classification head of YOLOs. The new kernel parameters K′ ∈ R C×D′×1×1 for last convolution layer after re-parameterization can be derived by
此外,训练完成后,辅助网络可以与物体嵌入头重参数化为与 YOLO 完全相同的分类头。重参数化后最后一层卷积层的新核参数 K′ ∈ R C×D′×1×1 可通过下式推导:
The final predication can be obtained by Label = I ⊛K′, which is identical to the original YOLO architecture, leading to zero overhead for deployment and transferring to downstream closed-set tasks.
最终预测可通过 Label = I ⊛K′ 获得,这与原始 YOLO 架构完全一致,从而在部署和迁移到下游闭集任务时实现零开销。
3.3 语义激活的视觉提示编码器
Visual prompts are designed to indicate the object category of interest through visual cues, e.g., box and mask. To produce the visual prompt embedding, prior works often employ transformer-heavy design [20, 30], e.g., deformable attention [78], or additional CLIP vision encoder [44, 67]. These ways, however, introduce challenges in deployment and efficiency due to complex operators or high computational demands. Considering this, we introduce Semantic-Activated Visual Prompt Encoder (SAVPE) for efficiently processing visual cues. It features two decoupled lightweight branches: (1) Semantic branch outputs prompt-agnostic semantic features in D channels without overhead of fusing visual cues, and (2) Activation branch produces grouped prompt-aware weights by interacting visual cues with image features in much fewer channels under low costs. Their aggregation then leads to informative prompt embedding under minimal complexity.
视觉提示旨在通过视觉线索(如框和掩膜)指示感兴趣的物体类别。为了生成视觉提示嵌入,先前的工作通常采用重 Transformer 设计 [20, 30](如可变形注意力 [78])或额外的 CLIP 视觉编码器 [44, 67]。然而,由于复杂的算子或高计算需求,这些方式在部署和效率上带来挑战。考虑到这一点,我们引入语义激活的视觉提示编码器(SAVPE)来高效处理视觉线索。它具有两个解耦的轻量分支:(1) 语义分支在 D 个通道中输出与提示无关的语义特征,无需融合视觉线索的开销;(2) 激活分支通过视觉线索与图像特征在远少于 D 的通道中交互,以低成本产生分组的提示感知权重。两者的聚合以最小复杂度得到信息丰富的提示嵌入。
As shown in Fig. 3.(b), in the semantic branch, we adopt the similar structure as object embedding head. With multi-scale features {P3, P4, P5} from PAN, we employ two 3×3 convs for each scale, respectively. After upsampling, features are concatenated and projected to derive semantic features S ∈ R D×H×W. In the activation branch, we formalize visual prompt as mask with 1 for indicated region and 0 for others. We downsample it and leverage 3×3 conv to derive prompt feature FV ∈ R A×H×W. Besides, we obtain image features FI ∈ R A×H×W for fusion with it from {P3, P4, P5} by convs. FV and FI are then concatenated and utilized to output prompt-aware weights W ∈ R A×H×W, which is normalized using softmax within prompt-indicated region. Moreover, we divide the channels of S into A groups with D/A channels in each. The channels in the i-th group share the weight Wi:i+1 from the i-th channel of W. With A ≪ D, we can process visual cues with image features in low dimension, bringing minimal cost. Furthermore, prompt embedding can be derived with aggregation of two branches by
如图 3.(b) 所示,在语义分支中,我们采用与物体嵌入头相似的结构。利用来自 PAN 的多尺度特征 {P3, P4, P5},我们分别对每个尺度使用两个 3×3 卷积。上采样后,特征被拼接并投影,得到语义特征 S ∈ R D×H×W。在激活分支中,我们将视觉提示形式化为掩膜,指示区域为 1,其他区域为 0。我们对掩膜进行下采样,并利用 3×3 卷积得到提示特征 FV ∈ R A×H×W。此外,我们通过卷积从 {P3, P4, P5} 中获得图像特征 FI ∈ R A×H×W 与之融合。FV 和 FI 随后被拼接,用于输出提示感知权重 W ∈ R A×H×W,并在提示指示区域内用 softmax 进行归一化。此外,我们将 S 的通道划分为 A 组,每组 D/A 个通道。第 i 组的通道共享 W 第 i 个通道的权重 Wi:i+1。由于 A ≪ D,我们可以在低维度下处理视觉线索与图像特征,带来极小的成本。进一步地,提示嵌入可通过两个分支的聚合得到:
It can thus contrast with anchor points’ object embeddings to identify objects with category of interest.
它可以与锚点的物体嵌入进行对比,以识别具有感兴趣类别的物体。
3.4 惰性区域-提示对比
In prompt-free scenario without explicit guidance, models are expected to identity all objects with names in the image. Prior works usually formulate such setting as a generative problem, where language model is employed to generate categories for dense found objects [33, 49, 62]. However, this introduces notable overhead, where language models, e.g., FlanT5-base [6] with 250M parameters in GenerateU [33] and OPT-125M [73] in DINO-X [49], are far from meeting high efficiency requirement. Given this, we reformulate such setting as a retrieval problem and present Lazy Region-Prompt Contrast (LRPC) strategy. It lazily retrieves category names from a built-in large vocabulary for anchor points with objects in the cost-effective way. Such paradigm enjoys zero dependency on language models, meanwhile with favorable efficiency and performance.
在无显式引导的无提示场景中,模型需要识别图像中所有物体及其名称。先前的工作通常将这种设置表述为生成式问题,利用语言模型为密集找到的物体生成类别 [33, 49, 62]。然而,这带来了显著的开销——GenerateU [33] 中的 FlanT5-base [6](250M 参数)和 DINO-X [49] 中的 OPT-125M [73] 等语言模型远不能满足高效率要求。为此,我们将该设置重新表述为检索问题,并提出惰性区域-提示对比(LRPC)策略。它以低成本的方式,为有物体的锚点从内置大词汇表中惰性地检索类别名称。这种范式完全不依赖语言模型,同时具备良好的效率和性能。
Specifically, with pretrained YOLOE, we introduce a specialized prompt embedding and train it exclusively to find all objects, where objects are treated as one category. Meanwhile, we follow [16] to collect a large vocabulary which covers various categories and serve as the built-in data source for retrieval. One may directly leverage the large vocabulary as text prompts for YOLOE to identify all objects, which, however, incurs notable computational cost by contrasting abundant anchor points’ object embeddings with numerous textual embeddings. Instead, we employ the specialized prompt embedding Ps to find the set O′ of anchor points corresponding to objects by
具体来说,基于预训练的 YOLOE,我们引入一个专用提示嵌入,并专门训练它来找到所有物体,其中物体被视为单一类别。同时,我们遵循 [16] 收集了一个覆盖各类别的大词汇表,作为检索的内置数据源。可以直接将大词汇表作为 YOLOE 的文本提示来识别所有物体,但这需要将大量锚点的物体嵌入与众多文本嵌入进行对比,带来显著的计算成本。取而代之,我们使用专用提示嵌入 Ps 来找到与物体对应的锚点集合 O′:
where O denotes all anchor points and δ is the threshold hyperparameter for filtering. Then, only anchor points in O′ are lazily matched against the built-in vocabulary to retrieve category names, bypassing the cost for irrelevant anchor points. This further improves efficiency without performance drop, facilitating the real world application.
其中 O 表示所有锚点,δ 是用于过滤的阈值超参数。然后,仅将 O′ 中的锚点与内置词汇表进行惰性匹配以检索类别名称,绕过了无关锚点的计算成本。这进一步提高了效率且不损失性能,促进了实际应用。
3.5 训练目标
During training, we follow [5] to obtain an online vocabulary for each mosaic sample with the texts involved in the images as positive labels. Following [21], we leverage task-aligned label assignment to match predictions with ground truths. The binary cross entropy loss is employed for classification, with IoU loss and distributed focal loss adopted for regression. For segmentation, we follow [3] to utilize binary cross-entropy loss for optimizing masks.
训练期间,我们遵循 [5],为每个 mosaic 样本构建在线词汇表,以图像中涉及的文本作为正标签。遵循 [21],我们利用任务对齐标签分配将预测与真值匹配。分类采用二值交叉熵损失,回归采用 IoU 损失和分布聚焦损失。对于分割,我们遵循 [3] 使用二值交叉熵损失优化掩膜。
4. Experiments
4.1 实现细节
Model. For fair comparison with [5], we employ the same YOLOv8 architecture [21] for YOLOE. Besides, to verify its good generalizability on other YOLOs, we also experiment with YOLO11 architecture [21]. For both of them, we provide three model scales, i.e., small (S), medium (M), and large (L), to suit various application needs. Text prompts are encoded using the pretrained MobileCLIP-B(LT) [57] text encoder. We empirically use A = 16 in SAVPE, by default.
模型。为了与 [5] 公平比较,YOLOE 采用相同的 YOLOv8 架构 [21]。此外,为了验证其对其他 YOLO 的良好泛化性,我们还使用 YOLO11 架构 [21] 进行了实验。两者都提供三个模型规模,即小(S)、中(M)和大(L),以适应各种应用需求。文本提示使用预训练的 MobileCLIP-B(LT) [57] 文本编码器进行编码。SAVPE 中默认使用 A = 16。
Data. We follow [5] to utilize detection and grounding datasets, including Objects365 (V1) [52], GoldG [22] (includes GQA [17] and Flickr30k [43]), where images from COCO [34] are excluded. Beside, we leverage advanced SAM-2.1 [46] model to generate pseudo instance masks using ground truth bounding boxes from the detection and grounding datasets for segmentation data. These masks undergo filtering and simplification to eliminate noise [9]. For visual prompt data, we follow [20] to leverage ground truth bounding boxes for visual cues. In prompt-free tasks, we reuse the same datasets, but annotate all objects as a single category to learn a specialized prompt embedding.
数据。我们遵循 [5] 使用检测和 grounding 数据集,包括 Objects365 (V1) [52]、GoldG [22](包含 GQA [17] 和 Flickr30k [43]),其中排除了 COCO [34] 的图像。此外,我们利用先进的 SAM-2.1 [46] 模型,使用检测和 grounding 数据集中的真值边界框生成伪实例掩膜作为分割数据。这些掩膜经过过滤和简化以消除噪声 [9]。对于视觉提示数据,我们遵循 [20] 使用真值边界框作为视觉线索。在无提示任务中,我们复用相同的数据集,但将所有物体标注为单一类别,以学习专用提示嵌入。
Training. Due to limited computational resource, unlike YOLO-World’s training for 100 epochs, we first train YOLOE with text prompts for 30 epochs. Then, we only train the SAVPE for merely 2 epochs with visual prompts, which avoids additional significant training cost that comes with supporting visual prompts. At last, we train the specialized prompt embedding for only 1 epoch for prompt-free scenarios. During the text prompt training stage, we adopt the same settings as [5]. Notably, YOLOE-v8-S / M / L can be trained on 8 Nvidia RTX4090 GPUs in 12.0 / 17.0 / 22.5 hours, with 3× less cost compared with YOLO-World. For visual prompt training, we freeze all other parts and adopt the same setting as in text prompt training. To enable prompt-free capability, we leverage the same data to train a specialized embedding. We can see that YOLOE not only enjoys low training costs but also show exceptional zero-shot performance. Besides, to verify YOLOE’s good transferability on downstream tasks, we fine-tune our YOLOE on COCO [34] for closed-set detection and segmentation. We experiment with two distinct practical fine-tuning strategies: (1) Linear probing: Only the classification head is learnable and (2) Full tuning: All parameters are trainable. For Linear probing, we train all models for only 10 epochs. For Full tuning, we train small scale models including YOLOE-v8-S / 11-S for 160 epochs, and medium and large scale models including YOLOE-v8-M / L and YOLOE-11-M / L for 80 epochs, respectively.
训练。由于计算资源有限,与 YOLO-World 训练 100 个 epoch 不同,我们首先用文本提示训练 YOLOE 30 个 epoch。然后,仅用视觉提示训练 SAVPE 2 个 epoch,避免了支持视觉提示带来的额外显著训练成本。最后,针对无提示场景,仅用 1 个 epoch 训练专用提示嵌入。在文本提示训练阶段,我们采用与 [5] 相同的设置。值得注意的是,YOLOE-v8-S / M / L 可以在 8 块 Nvidia RTX4090 GPU 上分别用 12.0 / 17.0 / 22.5 小时完成训练,与 YOLO-World 相比成本低 3 倍。对于视觉提示训练,我们冻结所有其他部分,采用与文本提示训练相同的设置。为了启用无提示能力,我们利用相同的数据训练专用嵌入。可以看到,YOLOE 不仅享有低训练成本,还表现出出色的零样本性能。此外,为了验证 YOLOE 在下游任务上的良好可迁移性,我们在 COCO [34] 上微调 YOLOE 进行闭集检测和分割。我们实验了两种不同的实用微调策略:(1) 线性探测:仅分类头可学习;(2) 全量微调:所有参数可训练。对于线性探测,我们只训练所有模型 10 个 epoch。对于全量微调,小规模模型(包括 YOLOE-v8-S / 11-S)训练 160 个 epoch,中大规模模型(包括 YOLOE-v8-M / L 和 YOLOE-11-M / L)分别训练 80 个 epoch。
Metric. For text prompt evaluation, we utilize all category names from the benchmark as inputs, adhering to the standard protocol for open-vocabulary object detection tasks. For visual prompt evaluation, following [20], for each category, we randomly sample N training images (N=16 by default), extract visual embeddings using their ground truth bounding boxes, and compute the average prompt embedding. For prompt-free evaluation, we employ the same protocol as [33]. A pretrained text encoder [57] is employed to map open-ended predictions to semantically similar category names within the benchmark. In contrast to [33], we streamline the mapping process by selecting the most confident prediction, and eliminating the need for top-k selection and beam search. We use the tag list from [16] as the built-in large vocabulary with total 4585 category names, and empirically use δ = 0.001 for LRPC, by default. For all three prompt types, following [5, 20, 33], evaluations are conducted on LVIS [14] in a zero-shot manner, which contains 1,203 categories. By default, Fixed AP [7] on LVIS minival subset is reported. For transferring to COCO, standard AP is evaluated, following [1, 21]. Besides, we measure the FPS for all models on Nvidia T4 GPU with TensorRT and mobile device iPhone 12 with CoreML.
指标。对于文本提示评估,我们使用基准中的所有类别名称作为输入,遵循开放词汇物体检测任务的标准协议。对于视觉提示评估,遵循 [20],对每个类别随机采样 N 张训练图像(默认 N=16),使用其真值边界框提取视觉嵌入,并计算平均提示嵌入。对于无提示评估,我们采用与 [33] 相同的协议,使用预训练文本编码器 [57] 将开放式预测映射到基准中语义相似的类别名称。与 [33] 不同的是,我们通过选择置信度最高的预测来简化映射过程,无需 top-k 选择和束搜索。我们使用 [16] 的标签列表作为内置大词汇表,共 4585 个类别名称,LRPC 默认使用 δ = 0.001。对于三种提示类型,遵循 [5, 20, 33],在包含 1,203 个类别的 LVIS [14] 上以零样本方式进行评估。默认报告 LVIS minival 子集上的 Fixed AP [7]。迁移到 COCO 时,遵循 [1, 21] 评估标准 AP。此外,我们在 Nvidia T4 GPU(TensorRT)和移动设备 iPhone 12(CoreML)上测量所有模型的 FPS。
4.2 文本和视觉提示评估
As shown in Tab. 1, for detection on LVIS, YOLOE exhibits favorable trade-offs between efficiency and zero-shot performance across different model scales. We also note that such results are achieved under much less training time, e.g., 3× faster than YOLO-Worldv2. Specifically, YOLOE-v8-S / M / L outperforms YOLOv8-Worldv2-S / M / L by 3.5 / 0.2 / 0.4 AP, along with 1.4× / 1.3× / 1.3× and 1.3× / 1.2× / 1.2× inference speedups on T4 and iPhone 12, respectively. Besides, for rare category which is challenging, our YOLOE-v8-S and YOLOE-v8-L obtains significant improvements of 5.2% and 7.6% APr. Besides, compared with YOLO-Worldv2, while YOLOE-v8-M / L achieves lower APf, this performance gap primarily stems from YOLOE’s integration of both detection and segmentation in one model. Such multi-task learning introduces a trade-off that adversely impact detection performance on frequent categories, as shown in Tab. 5. Besides, YOLOE with YOLO11 architecture also exhibits favorable performance and efficiency. For example, YOLOE-11-L achieves comparable AP with YOLO-Worldv2-L, but with notably 1.6× inference speedups on T4 and iPhone 12, highlighting the strong generalizability of our YOLOE.
如表 1 所示,对于 LVIS 上的检测,YOLOE 在不同模型规模之间展现出效率与零样本性能的良好权衡。我们还注意到,这些结果是在少得多的训练时间下取得的,例如比 YOLO-Worldv2 快 3 倍。具体来说,YOLOE-v8-S / M / L 分别超越 YOLO-Worldv2-S / M / L 达 3.5 / 0.2 / 0.4 AP,并在 T4 和 iPhone 12 上分别获得 1.4× / 1.3× / 1.3× 和 1.3× / 1.2× / 1.2× 的推理加速。此外,对于具有挑战性的稀有类别,YOLOE-v8-S 和 YOLOE-v8-L 分别获得了 5.2% 和 7.6% 的显著 APr 提升。此外,与 YOLO-Worldv2 相比,虽然 YOLOE-v8-M / L 的 APf 较低,但这一性能差距主要源于 YOLOE 在单一模型中同时集成了检测和分割。如 Tab. 5 所示,这种多任务学习引入了权衡,对常见类别的检测性能产生了不利影响。此外,采用 YOLO11 架构的 YOLOE 也表现出良好的性能和效率。例如,YOLOE-11-L 达到了与 YOLO-Worldv2-L 相当的 AP,但在 T4 和 iPhone 12 上获得了显著的 1.6 倍推理加速,凸显了 YOLOE 的强大泛化性。
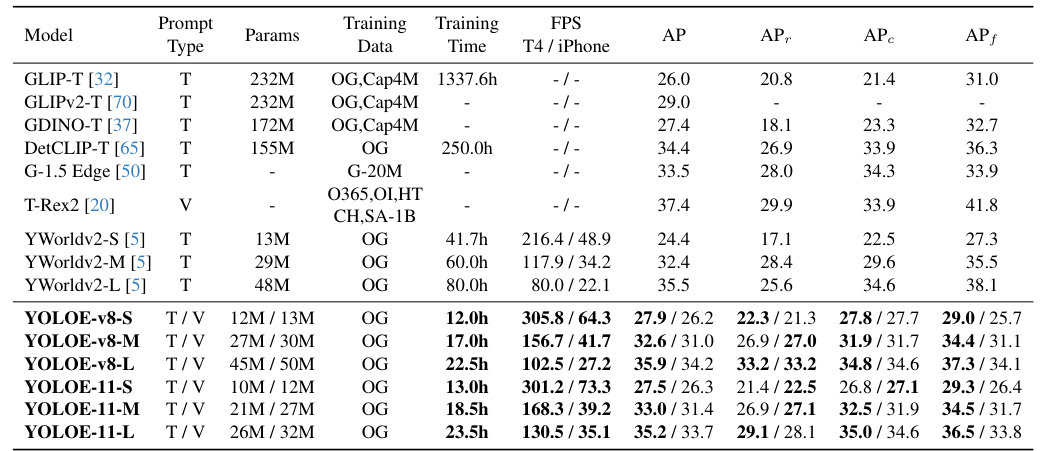
Moreover, the inclusion of visual prompts further amplifies YOLOE’s versatility. Compared with T-Rex2, YOLOE-v8-L yield the improvements of 3.3 APr and 0.9 APc, with 2× less training data (3.1 M vs. Our: 1.4 M) and much lower training resource (16 Nvidia A100 GPUs vs. Our: 8 Nvidia RTX4090 GPUs). Besides, for visual prompts, while we only train SAVPE with other parts frozen for 2 epochs, we note that it can achieve comparable APr and APc with the text prompts for various model scales. This shows the efficacy of visual prompts in less frequent objects that text prompts often struggle to accurately describe, which is similar to the observation in [20].
此外,视觉提示的加入进一步增强了 YOLOE 的多功能性。与 T-Rex2 相比,YOLOE-v8-L 获得了 3.3 APr 和 0.9 APc 的提升,训练数据少 2 倍(3.1M vs. 我们:1.4M),训练资源也低得多(16 块 Nvidia A100 GPU vs. 我们:8 块 Nvidia RTX4090 GPU)。此外,对于视觉提示,虽然我们仅在冻结其他部分的情况下训练 SAVPE 2 个 epoch,但注意到它在各种模型规模上可以达到与文本提示相当的 APr 和 APc。这表明视觉提示对于文本提示通常难以准确描述的低频物体是有效的,这与 [20] 中的观察类似。
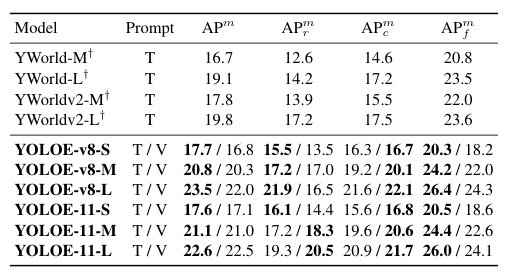
Furthermore, for segmentation, we present the evaluation results on the LVIS val set with the standard APm reported in Tab. 2. It shows that YOLOE exhibits strong performance by leveraging both text prompts and visual prompts. Specifically, YOLOE-v8-M / L achieves 20.8 and 23.5 APm in the zero-shot manner, significantly outperforming YOLO-Worldv2-M / L that is fine-tuned on LVIS-Base dataset, by 3.0 and 3.7 APm, respectively. These results well show the superiority of YOLOE.
此外,对于分割,我们在 LVIS val 集上报告标准 APm 的评估结果,如表 2 所示。结果表明,YOLOE 通过同时利用文本提示和视觉提示表现出强大的性能。具体来说,YOLOE-v8-M / L 以零样本方式分别达到 20.8 和 23.5 APm,显著超越在 LVIS-Base 数据集上微调的 YOLO-Worldv2-M / L,分别高出 3.0 和 3.7 APm。这些结果充分展示了 YOLOE 的优越性。
4.3 无提示评估
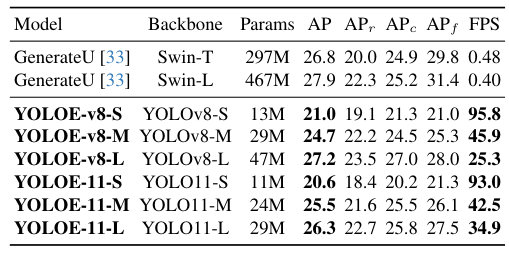
As shown in Tab. 3, for prompt-free scenario, YOLOE also exhibits superior performance and efficiency. Specifically, YOLO-v8-L achieves 27.2 AP and 23.5 APr, outperforming GenerateU with Swin-T backbone by 0.4 AP and 3.5 APr, along with 6.3× fewer parameters and 53× inference speedups. It shows the effectiveness of YOLOE by reformulating the open-ended problem as the retrieval task for a built-in large vocabulary and underscores its potential in generalizing across a wide range of categories without replying on explicit prompts. Such functionality also enhances YOLOE’s practicality, enabling its application in a broader range of real-world scenarios.
如表 3 所示,对于无提示场景,YOLOE 同样表现出卓越的性能和效率。具体来说,YOLO-v8-L 达到 27.2 AP 和 23.5 APr,以 6.3 倍少的参数量和 53 倍的推理加速,超越 Swin-T 骨干的 GenerateU 达 0.4 AP 和 3.5 APr。这表明 YOLOE 通过将开放式问题重新表述为针对内置大词汇表的检索任务的有效性,并凸显了其在无需依赖显式提示的情况下泛化到广泛类别的潜力。这种功能也增强了 YOLOE 的实用性,使其能够应用于更广泛的现实场景。
4.4 下游迁移
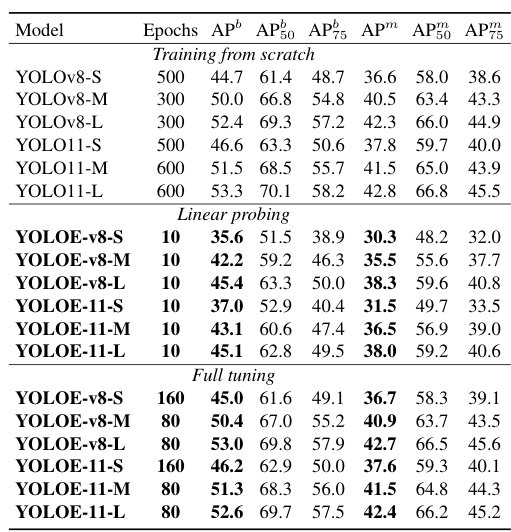
As shown in Tab. 4, when transferring to COCO for downstream closed-set detection and segmentation, YOLOE exhibits favorable performance under limited training epochs in both two fine-tuning strategies. Specifically, for Linear probing, with less than 2% of the training time, YOLOE-11-M / L can achieve over 80% of the performance of YOLO11-M / L, respectively. This highlights the strong transferability of YOLOE. For Full tuning, YOLOE can further enhance the performance under limited training cost. For example, with nearly 4× less training epochs, YOLOE-v8-M / L outperforms YOLOv8-M / L by 0.4 APm and 0.6 APb, respectively. Under 3× less training time, YOLO-v8-S also obtains better performance compared with YOLOv8-S for both detection and segmentation. These results well demonstrate that YOLOE can serve as a strong starting point for transferring to downstream task.
如表 4 所示,迁移到 COCO 进行下游闭集检测和分割时,YOLOE 在两种微调策略下、有限的训练 epoch 内均表现出良好的性能。具体来说,对于线性探测,YOLOE-11-M / L 用不到 2% 的训练时间分别达到 YOLO11-M / L 超过 80% 的性能,凸显了 YOLOE 的强大可迁移性。对于全量微调,YOLOE 可以在有限的训练成本下进一步提升性能。例如,YOLOE-v8-M / L 以近 4 倍少的训练 epoch,分别超越 YOLOv8-M / L 达 0.4 APm 和 0.6 APb。在 3 倍少的训练时间下,YOLO-v8-S 在检测和分割上也获得了比 YOLOv8-S 更好的性能。这些结果充分表明,YOLOE 可以作为迁移到下游任务的强大起点。
4.5 消融实验
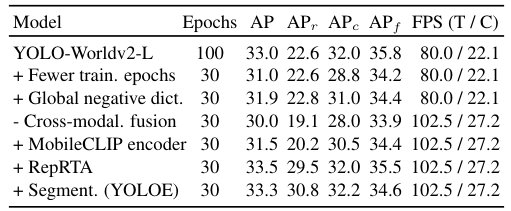
Roadmap to YOLOE. We outline the stepwise progression from the baseline model YOLOv8-Worldv2-L to our YOLOE-v8-L in terms of text prompts in Tab. 5. With the initial baseline metric of 33.0% AP, due to limited computational resource, we first reduce the training epochs to 30, leading to 31.0% AP. Besides, instead of using empty string as negative texts for grounding data, we follow [65] by maintaining a global dictionary to sample more diverse negative prompts. The global dictionary is constructed by selecting category names that appear more than 100 times in the training data. This leads to 0.9% AP improvement. Next, we remove the cross-modality fusion to avoid costly visual-textual feature interaction, which results in 1.9% AP degradation but with 1.28× and 1.23× inference speedups on T4 and iPhone 12, respectively. To address this drop, we utilize stronger MobileCLIP-B(LT) text encoder [57] to obtain better pretrained textual embeddings, which recovers AP to 31.5%. Furthermore, we employ RepRTA to enhance the alignment between anchor points’ object and textual embeddings, which leads to notable 2.3% AP enhancement with zero inference overhead, showing its effectiveness. At last, we introduce the segmentation head and train YOLOE for detection and segmentation simultaneously. Although this leads to 0.2% AP and 0.9 APf drop due to multi-task learning, YOLOE gains ability to segment arbitrary objects.
YOLOE 的演进路线。我们在 Tab. 5 中概述了从基线模型 YOLO-Worldv2-L 到 YOLOE-v8-L 的逐步演进(文本提示维度)。基线指标为 33.0% AP。由于计算资源有限,我们首先将训练 epoch 减少到 30,得到 31.0% AP。此外,我们不再使用空字符串作为 grounding 数据的负样本文本,而是遵循 [65] 维护一个全局字典来采样更多样化的负提示。全局字典由训练数据中出现次数超过 100 次的类别名称构成,带来了 0.9% AP 的提升。接下来,我们移除跨模态融合以避免昂贵的视觉-文本特征交互,导致 1.9% AP 下降,但在 T4 和 iPhone 12 上分别获得了 1.28 倍和 1.23 倍的推理加速。为了解决这一下降,我们使用更强的 MobileCLIP-B(LT) 文本编码器 [57] 获得更好的预训练文本嵌入,将 AP 恢复到 31.5%。进一步地,我们使用 RepRTA 增强锚点物体嵌入与文本嵌入之间的对齐,在零推理开销下带来显著的 2.3% AP 提升,展示了其有效性。最后,我们引入分割头,同时训练 YOLOE 进行检测和分割。虽然由于多任务学习导致 0.2% AP 和 0.9 APf 的下降,但 YOLOE 获得了分割任意物体的能力。
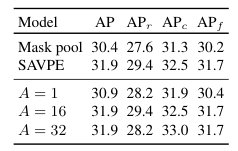
Effectiveness of SAVPE. To verify the effectiveness of SAVPE for visual inputs, we remove the activation branch and simply leverage mask pooling to aggregate semantic features with the formulated visual prompt mask. As shown in Tab. 6, SAVPE significantly outperforms “Mask pool” by 1.5 AP. This is because “Mask pool” neglects the varying semantic importance at different positions within prompt-indicated region, while our activation branch effectively models such difference, leading to improved aggregation of semantic features and better prompt embedding for contrast. We also examine the impact of different group numbers, i.e., A, in the activation branch. As shown in Tab. 6, performance can also be enhanced with only a group, i.e., A = 1. Besides, we can achieve the strong performance of 31.9 AP under A = 16, obtaining the favorable balance, where more groups lead to marginal performance difference.
SAVPE 的有效性。为了验证 SAVPE 对视觉输入的有效性,我们移除激活分支,仅使用掩膜池化(mask pooling)按构造的视觉提示掩膜聚合语义特征。如表 6 所示,SAVPE 显著超越「Mask pool」达 1.5 AP。这是因为「Mask pool」忽略了提示指示区域内不同位置语义重要性的差异,而激活分支有效地建模了这种差异,从而改进了语义特征的聚合,得到更好的对比提示嵌入。我们还考察了激活分支中不同分组数 A 的影响。如表 6 所示,仅用一个分组(A = 1)也能提升性能。此外,在 A = 16 时可以达到 31.9 AP 的强劲性能,获得了良好的平衡,更多分组带来的性能差异很小。
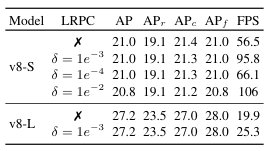
Effectiveness of LRPC. To verify the effectiveness of LRPC for prompt-free setting, we introduce the baseline that directly leverage the built-in large vocabulary as text prompts for YOLOE to identify all objects. Tab. 7 presents the comparison results. We observe that with the same performance, our LRPC obtains notably 1.7× / 1.3× inference speedups for YOLOE-v8-S / L, respectively, by lazily retrieving the categories for anchor points with found objects and skipping the numerous irrelevant ones. These results well highlight its efficacy and practicality. Besides, with different threshold δ for filtering, LRPC can achieve different performance and efficiency trade-offs, e.g., enabling 1.9× speedup for YOLOE-v8-S with only 0.2 AP drop.
LRPC 的有效性。为了验证 LRPC 在无提示设置下的有效性,我们引入直接将内置大词汇表作为 YOLOE 文本提示来识别所有物体的基线。Tab. 7 给出了对比结果。我们观察到,在相同性能下,LRPC 通过仅对找到物体的锚点惰性检索类别、跳过大量无关锚点,为 YOLOE-v8-S / L 分别带来了显著的 1.7 倍 / 1.3 倍推理加速。这些结果充分凸显了其有效性和实用性。此外,通过不同的过滤阈值 δ,LRPC 可以实现不同的性能与效率权衡,例如在仅有 0.2 AP 下降的情况下为 YOLOE-v8-S 实现 1.9 倍加速。
4.6 可视化分析
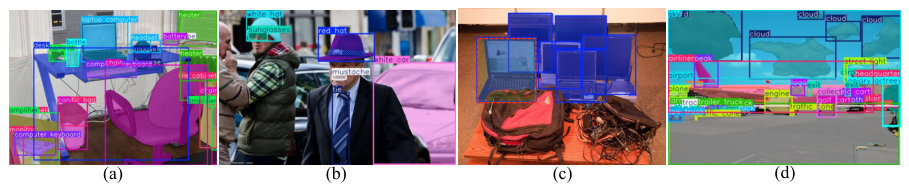
We conduct visualization analyses for YOLOE in four scenarios: (1) Zero-shot inference on LVIS in Fig. 4.(a), where its category names are text prompts, (2) Text prompts in Fig. 4.(b), where arbitrary texts can be input as prompts, (3) Visual prompts in Fig. 4.(c), where visual cues can be drawn as prompts, and (4) No explicit prompt in Fig. 4.(d), where model identifies all objects. We can see that YOLOE performs well and can accurately detect and segment various objects in these diverse scenarios, further showing its efficacy and practicality in various applications.
我们在四种场景下对 YOLOE 进行了可视化分析:(1) 图 4.(a) 中 LVIS 上的零样本推理,类别名称作为文本提示;(2) 图 4.(b) 中的文本提示,任意文本都可以作为提示输入;(3) 图 4.(c) 中的视觉提示,视觉线索可以绘制为提示;(4) 图 4.(d) 中的无显式提示,模型识别所有物体。可以看到,YOLOE 在这些多样化场景中表现良好,能够准确地检测和分割各种物体,进一步展示了其在各种应用中的有效性和实用性。
5. Conclusion
In this paper, we present YOLOE, a single highly efficient model that seamlessly integrates object detection and segmentation across diverse open prompt mechanisms. Specifically, we introduce RepRTA, SAVPE, and LRPC to enable YOLOs to process textual prompt, visual cues, and prompt-free paradigm with favorable performance and low cost. Thanks to them, YOLOE enjoys strong capabilities and high efficiency for various prompt ways, enabling real-time seeing anything. We hope that it can serve as a strong baseline to inspire further advancements.
本文提出 YOLOE,一个高效的单模型,无缝集成了跨多种开放提示机制的物体检测和分割。具体来说,我们引入 RepRTA、SAVPE 和 LRPC,使 YOLO 能够以良好的性能和低成本处理文本提示、视觉线索和无提示范式。得益于这些设计,YOLOE 在各种提示方式下都具备强大的能力和高效率,实现了实时”看见一切”。我们希望它能成为一个强大的基线,推动进一步发展。